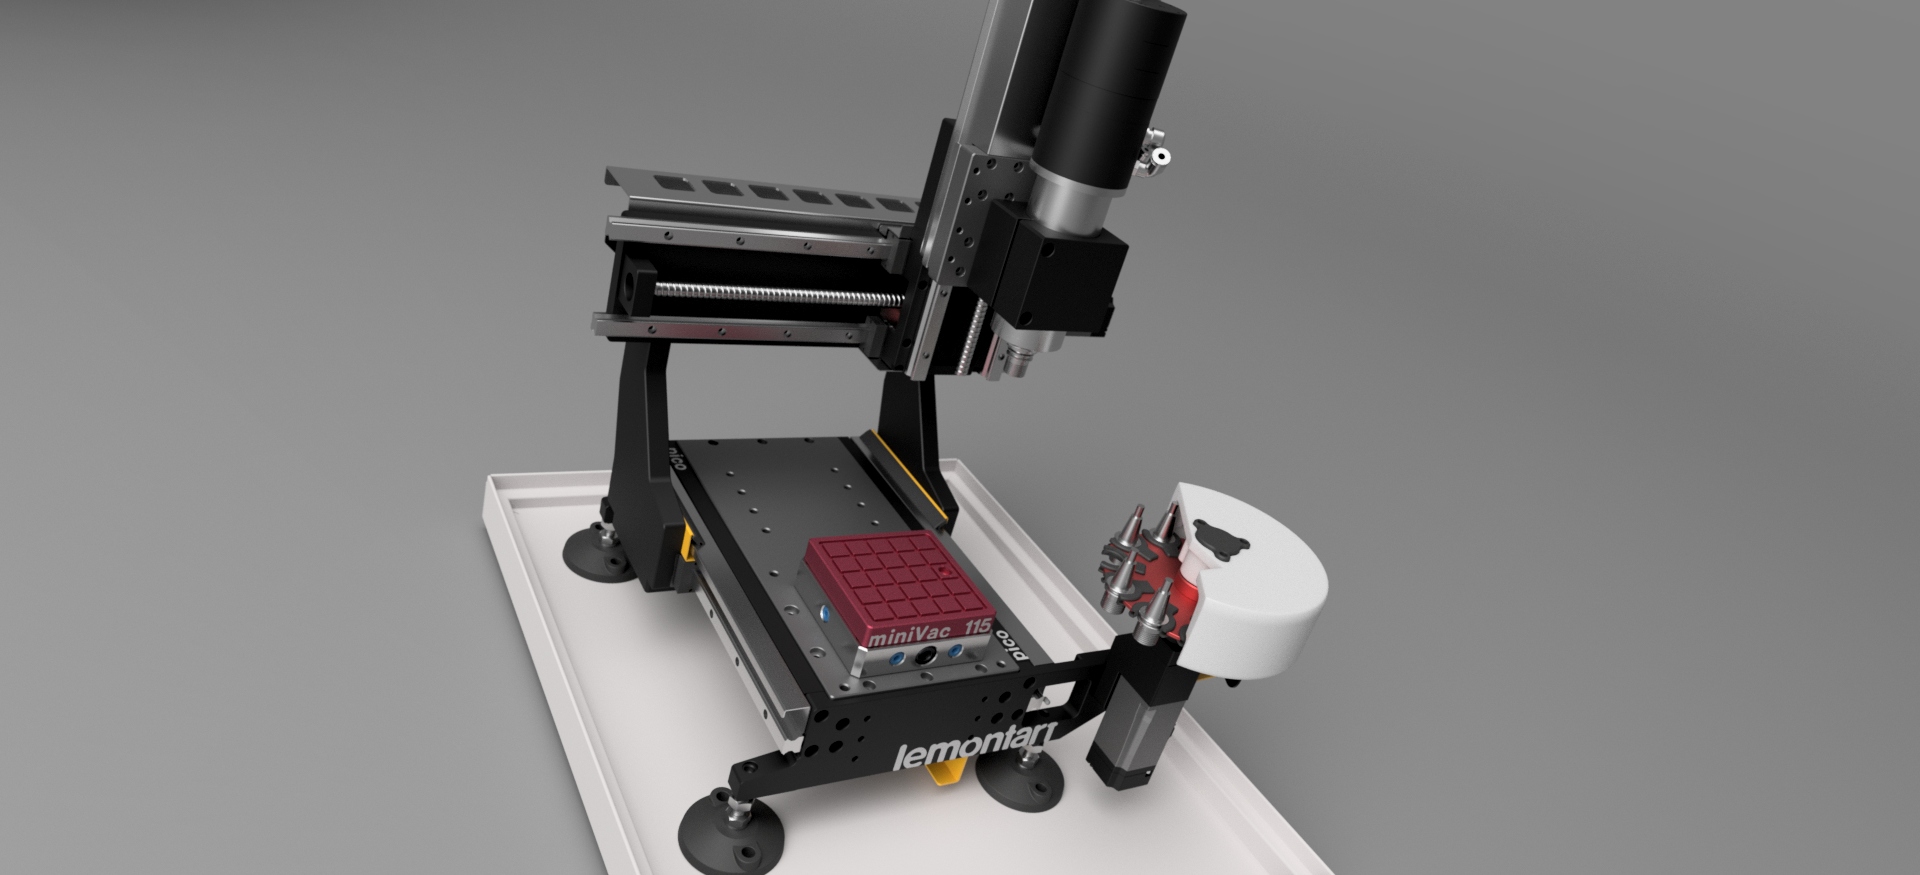
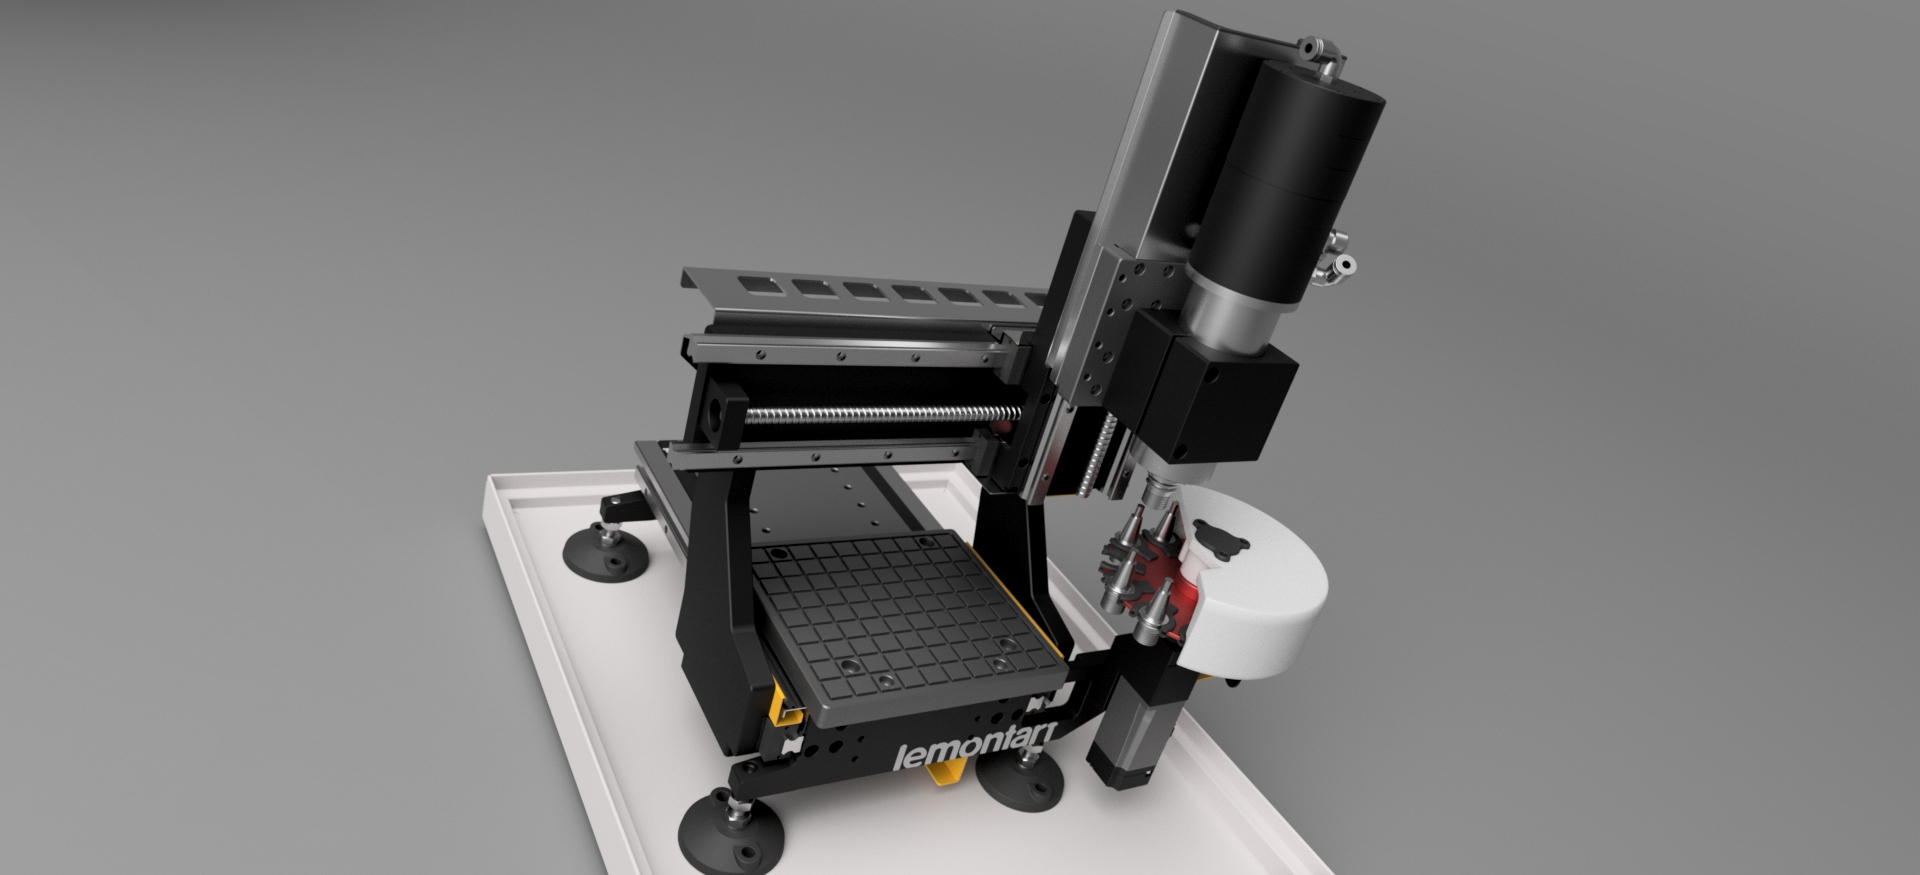
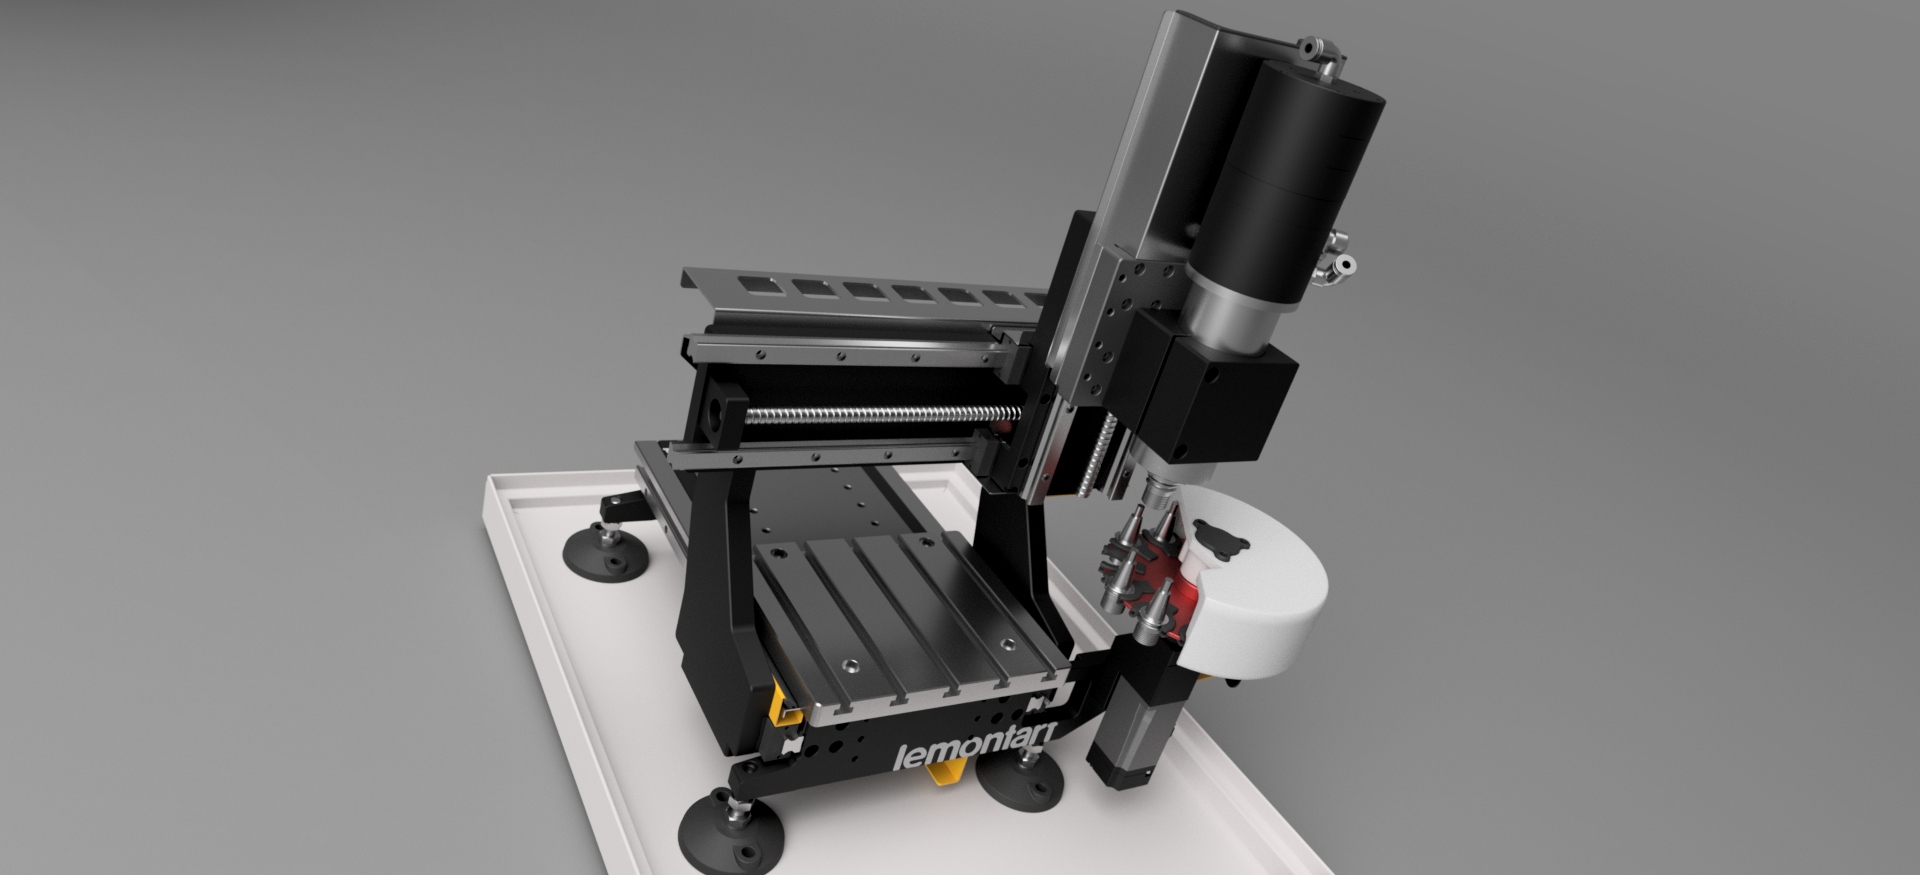
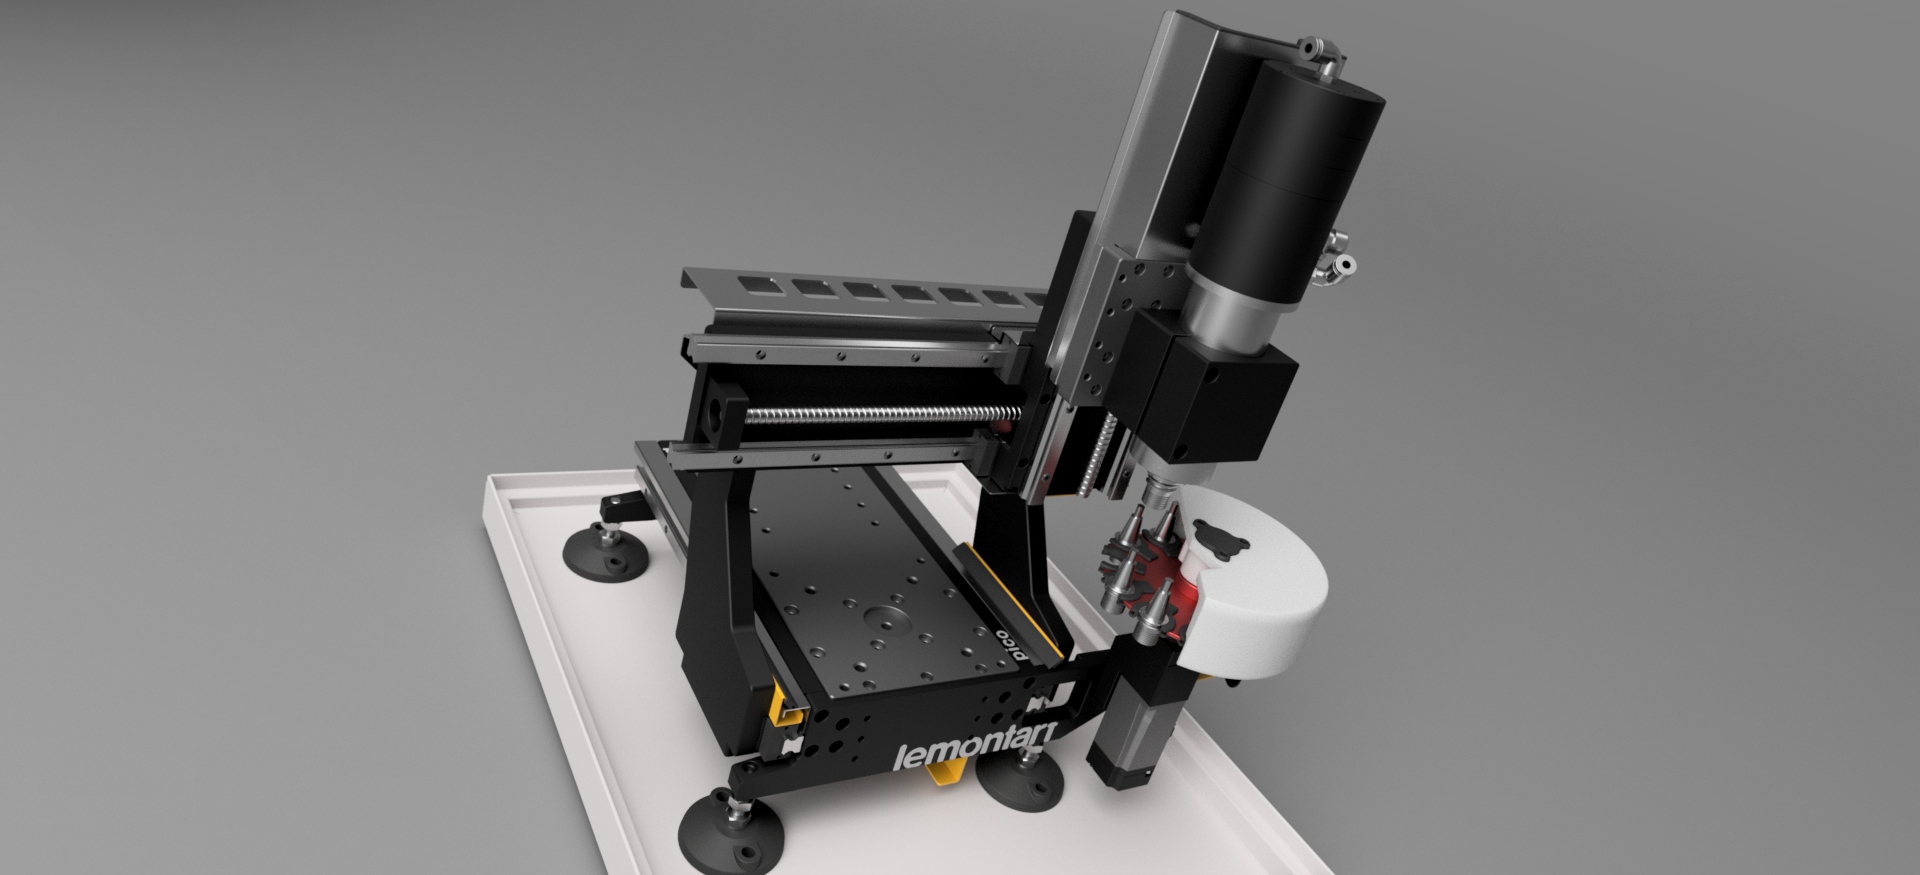
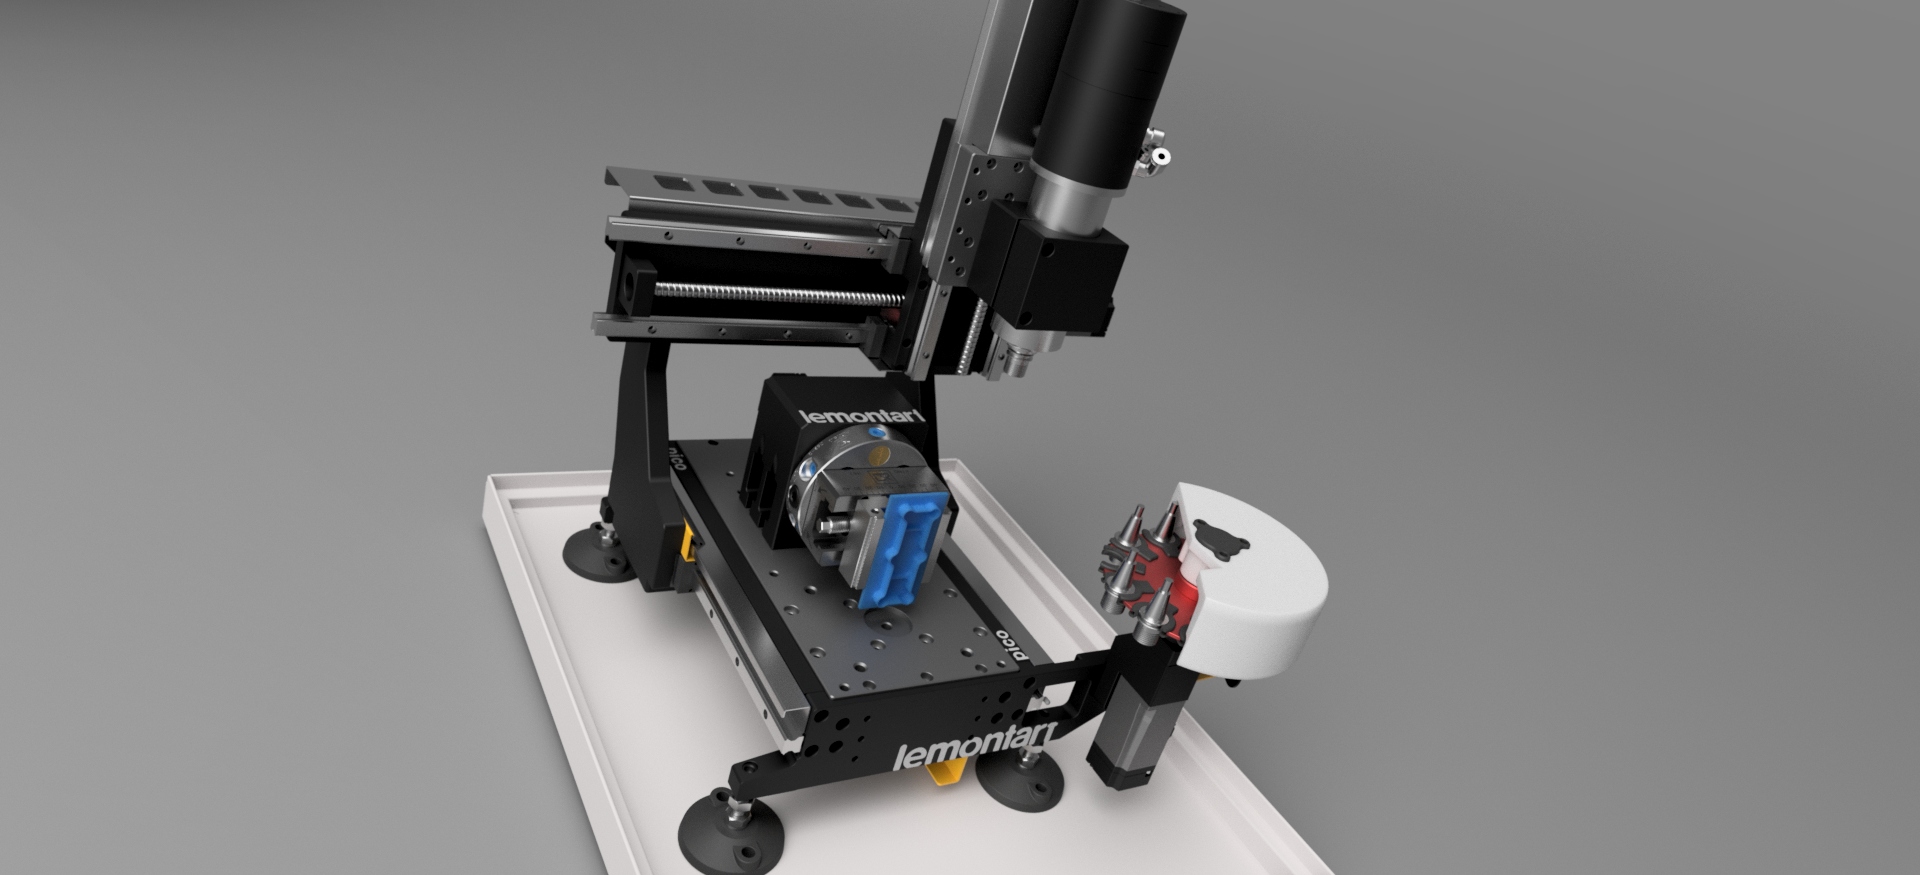
Mini wannabe datron build

More
3 months 1 week ago #347897 by ihavenofish
boink.
I think everything works now. got help with the correct updates on the ethercat patches/version. I geared down the 4th axis, so it can do 1600 turns now. not a proper fix, but it will get me cutting today and we can figure out a more correct rollover later.

As always, thanks for all the help.

Please Log in or Create an account to join the conversation.

More
3 months 1 week ago #347912 by ihavenofish
Or not. it still faults randomly on xyz. we did not find a fix, but we did find the "cause" and created a patch plan which I will do in the morning.

Basically, if you watch PLL error, you see occasional spikes. Spikes that hit a threshold of about 100000 (this number is relative to the refclocksynccycles) trigger a DC phased even dropping it to 0. these only last one frame. They do not seem to ordinarily cause an issue. Once in a while (could be a minute, could be an hour) we get a joint error on one or all of the xyz axes which are omron, but not the A which is leadshine. When you look at this error in the scope, it comes a few frames after a pll error spike, and it EITHER sends the position feedback to 32 bit int rollover, OR to 0. Hence, joint error. I did notice that SOMETIMES we get a bad position value that does NOT roll over or go to 0, and this then gets corrected the next frame, and there is no joint error.

We can induce more events by changing refclocksynccycles form -1 to 300, and a value of 1 totally prevents anything from starting for more than a few seconds.

Why this occurs seems to be about timing, or maybe interference or noise corrupting values. hard to say still. Why is it seeming to be only the omrons? Other people have reported joint errors as well, perhaps we need to compare notes.

ANYHOW... the solution is just to filter the "actual position" feedback and remove any invalid frames. They are pretty easy to spot, if you are at 8000000 counts, and suddenly it goes to 0, or 2.1 billion, we just replace that value with the previous. Since we are in CSP mode, this doesn't have any effect.

The filter needs to be a bit smart, and check back 3-4 frames I think to detect the trend of motion. I shall figure that out in the morning and once it works, post the hal file here so others with this issue can use it.

This should also at the same time eliminate idle random soft limit errors, which happen for the same reason. (it wont really help with soft limit errors when right on the limit of course)

Thanks for all the help in the various threads and discords.

The following user(s) said Thank You: NWE

Please Log in or Create an account to join the conversation.

More
3 months 1 week ago #347940 by ihavenofish
I've not thanks to my patch confirmed that the drives are resetting. statusword goes to 0. controlword to 6 on the same frame, just after the pll spike. on that same frame the encoder goes to 0 or somethings a random bad number.

Joint error does not always trip (without the patch). i guess it depends how long the drive takes to recover.

Im not monitoring to see if its one or all drives, in what order, is it only the omrons, what if i swap cables around, etc.

Fun fun.

Please Log in or Create an account to join the conversation.

More
3 months 1 week ago #347953 by ihavenofish
so, its now narrowed down to a random spike in lcec readalltime and writealltime

BUT, curiously the individual slave read/write-alltime pins show no spikes. so something outside is randomly hogging time which when it exceeds 1ms or so, tops the drive (sometimes its less, sometimes it can go more and not trip)

The leadshines don't seem to mind. the omrons are not tolerant unless i push sync0shift waaay up. its at 750k now and has not errored in an hour or more. at 100k it errors many times per second. at 300 then 500k it reduce, but it can still error several times in a few minutes.

Coupled with my filter on the encoder values, it seems basically "worked around" for now. even with the filter I was getting occasional joint errors when time spikes hit 1ms or more.

We did also remove things from sharing irqs. I'm not sure that did anything. Thats the trouble with random errors... they are so random.

Please Log in or Create an account to join the conversation.

More
3 months 1 week ago #347974 by ihavenofish


Yaaaay!

Please Log in or Create an account to join the conversation.

More
1 month 2 weeks ago #349635 by ihavenofish
beep boop... 


Please Log in or Create an account to join the conversation.

Time to create page: 0.590 seconds
Powered by Kunena Forum