LinuxCNC S-Curve Accelerations

More
7 months 3 days ago #344898 by grandixximo
switching live I think is last refinement, YangYang working in separating the TP on a separate thread, switching will be refined after that.
At least spiking is gone, the fall back messages with TP1 are expected, just debugs, will be removed in next PR I think, thank you for spending the time testing.
The following user(s) said Thank You: tommylight, pommen, MX_Master, endian

Please Log in or Create an account to join the conversation.

More
7 months 3 days ago - 7 months 3 days ago #344916 by endian
no problem .. you are welcome, I am proud to cooperate/test this feature for linuxcnc comunity... as you noticed, I am not soo focused in the perfect trajectory but mainly at timing stability... sometimes it's like chasing your own tail

its interesting job and I see many advantages ... I am using TP0 for lathe threading/synchronization of motion for now, but we will wait for new stuff I am looking forward ...

yes I saw but Yang Yang publish new crucking repo few days ago but I have not time to study it ...

Luca which will be the next steps now ?

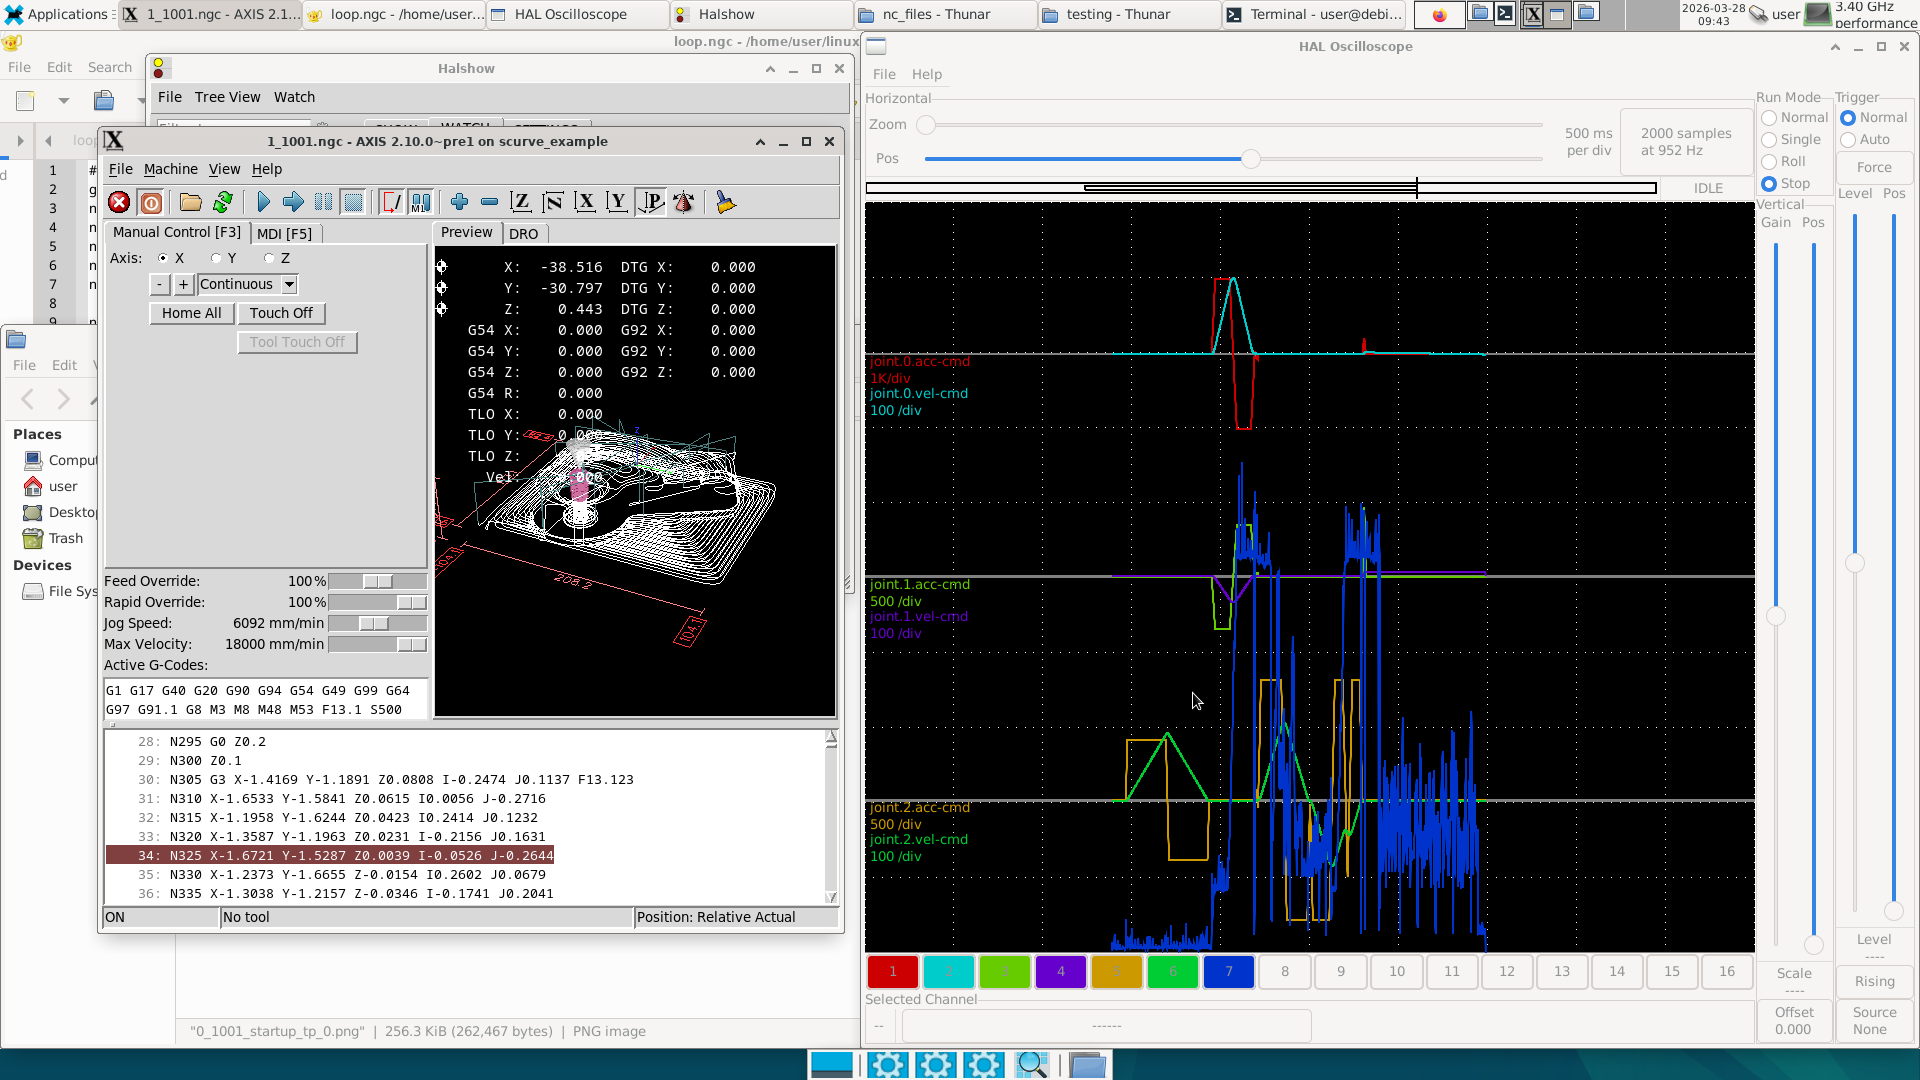
that dark blue spline at the bottom is the servo-thread.time, in the 100k resolution, which are sharply jumping at start of cloud of points as ... I am not pretty sure how the TP1 works to from the start but other files starting well without that spiking... is it possible to precalculated it or add some waiting to start the motion to smooth the beginning timing? 

How much influence latency of using Mate instead of Xfce gui ?
 
Last edit: 7 months 3 days ago by endian. Reason: 100k resolution adding

Please Log in or Create an account to join the conversation.

More
7 months 3 days ago #344928 by endian
Gemini tells me too...

The Problem: The 7-Phase WallWhen we move from traditional Trapezoidal (T-curve) to S-curve (Jerk-limited) motion, we hit a massive computational wall during High-Speed Machining (HSM). In a "cloud of points" (dense G-code with 0.01mm segments), a 3rd-order planner like the Yang Yang method has to solve a 7-phase analytical equation for every junction.At a 1ms servo thread, this is heavy. At 250µs, it’s nearly impossible for the CPU to stay in real-time. The result? "Unexpected Realtime Delays" or the planner "giving up" and slowing the feedrate (F) to a crawl to stay within Jerk limits.

The Best Available Solution: The "Double FIR" ApproachIf you are struggling with latency in your new S-curve trajectory planner, the most efficient implementation for dense point clouds isn't more complex math—it’s Digital Filtering.Instead of solving the 7-phase cubic equations at every point, the "Gold Standard" for high-frequency (250µs+) loops is the Double FIR (Finite Impulse Response) Filter:Trapezoidal Base: Use a simple, ultra-fast Trapezoidal planner to generate "raw" velocity.Filter 1: Pass the raw velocity through a moving average filter. This creates 2nd-order motion (Linear Acceleration).Filter 2: Pass that result through a second moving average filter. This creates 3rd-order motion (S-Curve / Jerk-limited).Why this wins for Point Clouds:O(1) Complexity: The math is just addition/subtraction. It doesn't care if the segment is 10mm or 0.001mm.Low Jitter: It’s perfectly suited for the 250µs window.Natural Blending: The filters act as a low-pass filter, naturally "smoothing" the noise inherent in point clouds without the overhead of junction-blending logic.

In professional controllers (Fanuc/Siemens), this is solved by having a dedicated DSP (Digital Signal Processor) or an FPGA that does nothing but the motion math, leaving the main CPU to handle the G-code.

Please Log in or Create an account to join the conversation.

More
7 months 2 days ago - 7 months 2 days ago #344934 by rodw
Replied by rodw on topic LinuxCNC S-Curve Accelerations
Interesting. If it helps, I have a well tested non-looping moving average function in a component for torch voltage here  github.com/rodw-au/showstopper/blob/mast...ents/ohmic3.comp#L92
If I wrote it today I would malloc the storage in the component's startup function instead of using fixed arrays.

Why can't you use more than one thread instead of a FGPA?

 
Last edit: 7 months 2 days ago by rodw.
The following user(s) said Thank You: akb1212, endian

Please Log in or Create an account to join the conversation.

More
7 months 2 days ago #344936 by rodw
Replied by rodw on topic LinuxCNC S-Curve Accelerations
by way of explanation the moving average uses a simple circular buffer and calculates the sum of readings. Once the buffer is filled, the next reading overwrites the first reading in the buffer. So by deducting that value before it is overwritten and adding the new value as its written, the sum is maintained without any loops. The moving average is simply the sum / buffer size. There is no reason why it could not be called again recursively to calculate the second moving average.
The following user(s) said Thank You: akb1212, endian

Please Log in or Create an account to join the conversation.

More
7 months 2 days ago #344939 by hmnijp

In professional controllers (Fanuc/Siemens), this is solved by having a dedicated DSP (Digital Signal Processor) or an FPGA that does nothing but the motion math, leaving the main CPU to handle the G-code.
As far as I know, that’s not entirely right.
For the nano-smoothing function (NURBS interpolation for cloud of points), Fanuc uses non-realtime buffered calculations on the CPU to prepare the trajectory (look-ahead buffer). Then, data from the interpolator is sent to the DSP, where the planner calculates the speeds in real time.
The following user(s) said Thank You: akb1212

Please Log in or Create an account to join the conversation.

Time to create page: 0.337 seconds
Powered by Kunena Forum